
Route the task
Choose a structure around the task's dependencies.
Deciding whether to accept an AI change? Paste its explanation, your goal and existing checks. Get a summary, missing information and questions to investigate. This template reviews text, not code.

Loading interactive sculpture
Click, Enter or Space pauses or plays motion. Drag or use arrow keys to rotate. Home resets the view. Decorative visualization, not live execution data.
THE AI'S EXPLANATION / EXAMPLE
“All tests passed.”
“The build looks good.”
“Everything is fixed.”
Which boundary cases and test results support the claimed fix?
Illustrative brief, not a customer result. This hosted template reviews supplied text only; it does not inspect code or verify correctness.
Read the full review brief →Connect from your agent, terminal or Python workflow. Each route leads to the same hosted execution records, with its own setup instructions.
See how to connect →The answer is only part of the story. Follow your agent’s work, inspect the checks that were available, and see what still needs your attention.
Select a node to inspect its record.
No sign-up for this demo. No code is executed.
Choose a scenario. Then follow the evidence.
Review the unrelated configuration change and the check that did not run. No merge or selection is performed.
Simulated playback / configured-runner example / not a customer result
A review layer, not another coding agent.
Follow one example from the text you provide to the review brief and the action you take next.
Add the AI's change explanation, your goal and anything you already checked. The selected model receives this supplied text.
Read a short summary, missing information and questions to investigate. The request, output and run status stay connected.
Inspect the suggested questions, check the code yourself and run the tests your repository needs. The template does not perform those checks.
GOAL
Review a pagination change before merging it.
AI EXPLANATION
Updated cursor pagination and added regression tests.
Already checked: the happy path only.
Repository code and test outputNOT INSPECTED
Summary: the change claims different cursor behavior and new regression coverage.
Missing: which boundary cases and test results support that claim?
Illustrative output from supplied text only. No repository, code or test results were inspected.
code_inspection: falseCreate your account, paste the explanation and add your goal and existing checks. The brief runs on the hosted model, so no provider key is needed.
Review my change explanationThis template reviews supplied text, not repository code. The hosted model is included in your plan. Repository checks require a separately configured execution environment.
An execution structure for the task, with outputs and evidence you can inspect.

Loading interactive sculpture
Click, Enter or Space pauses or plays motion. Drag or use arrow keys to rotate. Home resets the view. Decorative visualization, not live execution data.
Choose a structure around the task's dependencies.
Inspect agreement and disagreement, not a guarantee of correctness.
A completed run is not the same as a passed code check.
Several people reviewing AI coding agent changes? The Team plan shares one workspace, and MCP, CLI and SDK access fit into your existing tools. Repository checks need a separately configured execution environment.
AdaptOrch is a hosted review layer for AI coding agents. It records what ran, which checks were available and what still needs human review. MCP connects your tools; repository checks need a separately configured execution environment.
Starter is free with 50 admitted runs a month. Pro adds 500 runs and 5 workspace users. Hosted model usage is included; optional BYOK usage is billed by your provider. Code checks need a separately configured execution environment.
Connect from your agent, terminal or Python workflow. Each route leads to the same hosted execution records, with its own setup instructions.
AGENT CLIENT · HOSTED MCP
Connect an HTTP-capable MCP client to AdaptOrch. Submit a bounded run, then inspect the returned record and available artifacts.
Set up MCPHOSTED ENDPOINT
https://adaptorch.com/mcpAn AdaptOrch API key authenticates the service and runs work on the included hosted model. BYOK is optional; your provider bills that usage separately.
TERMINAL · HOSTED CLIENT
Use the hosted CLI client to work with run records from your terminal. Follow the setup guide for installation and supported commands.
Set up the CLITERMINAL SETUP PATH
Authenticate with AdaptOrch
Use the hosted model
Submit once. Inspect the returned record.
Authenticate the CLI with your AdaptOrch API key to use the hosted model. BYOK is optional. Follow the guide for installation and supported commands.
PYTHON · HOSTED CLIENT
Use the hosted Python client to submit bounded work and inspect the resulting records. Follow the guide for supported methods and request fields.
Set up the Python SDKPYTHON SETUP PATH
Authenticate with AdaptOrch
Use the hosted model
Submit once. Inspect the returned record.
The Python client authenticates with your AdaptOrch API key and runs on the hosted model. A successful request does not establish that code checks ran.
Choose the interface first. Configure the execution scope separately. Hosted command verification is disabled by default; a local client is not a self-hosted service.
Works beside the tools you already use


Compatible workflow surfaces; logos are not endorsements.
AVAILABLE HOSTED PATH
Use MCP or the API to submit model-backed work and retrieve run records, outputs and available artifacts. Starter is a free hosted plan.
SEPARATE SETUP / SCOPED POC
For repository and command checks, agree the environment, repository access, test commands and evidence handling first. A hosted plan upgrade does not enable this automatically.
Hosted runs send your inputs to AdaptOrch's model provider, so code does not stay on your device. Read the data-flow summary before sending inputs.
Data, security and operating responsibilities →Illustrative interactive example. No customer code or model call is executed by this button.
Choose an example scenario and replay the displayed steps. The demonstration uses fixed example data.
Candidate patch modifies astropy/table.py to repair issue
                  behavior.
The patch applies cleanly, but we cannot call it correct. The test evidence came back inconclusive, and the shadow check flagged repair risk with no reproducible run behind it.
Static example. Select Replay to step through the record.
A retry is still work. This sample keeps every attempt in view, and an unreported cost never becomes a zero.
Platform plan and model-provider charges are separate.
| CALL | ATTEMPT | SAMPLE ESTIMATE |
|---|---|---|
| Draft | 01 | $0.0048 |
| Review | 01 | $0.0021 |
| Summary | 01 | $0.0005 |
| Draft | 02 | $0.0048 |
| Review | 02 | Unreported |
| Summary | 02 | $0.0005 |
Earlier attempts stay in the record.
Illustrative model-call amounts in USD, not live prices, a bill, or a savings claim. Unreported calls are excluded from the subtotal, never treated as free.
Try a change explanation on Starter before choosing a paid hosted plan. Upgrade for more monthly runs or workspace users, not a correctness guarantee. The hosted model is included in every plan; your own provider bills you only if you bring your own key (BYOK).
Runs use AdaptOrch's hosted model (WorkBuddy deepseek-v4.1-flash), included in every plan with a run allowance. An AdaptOrch API key is all you need. Bring your own key (BYOK) stays optional for API callers who want their own provider account.
Optional ensemble fan-out calls 2–5 of your own models in a configured run. One admitted run uses one call from your plan quota; your provider bills the tokens for every member. Provider cost depends on the models, tokens and attempts. Workspace users are people, not ensemble model members. Agreement is not an accuracy guarantee.
Model outputs and AI-written explanations are AI-generated and require human review. They are not the same evidence as execution logs or results from checks that actually ran.
What each plan includes
Every plan runs on the hosted model and shows you the result. Pro and Team also show how the model reasoned, and explain the run in plain words.
| Feature | STARTER | PRO | TEAM |
|---|---|---|---|
| Hosted model runsdeepseek-v4.1-flash included · no provider key needed | Included | Included | Included |
| Answer and step-by-step outputSaved for every run · a short guide on how to read it | Included | Included | Included |
| Model reasoningNEWThe notes the main model wrote before answering | Not included | Included | Included |
| Plain-language explanationNEWWhat happened, what went wrong, how to fix it and what to check next, in your screen language · 30 per hour | Not included | Included | Included |
Model reasoning and plain-language explanations are written by AI. They can be wrong and are not evidence that the run’s result was checked.
Annual amounts are the full yearly charge in USD, not a monthly bill. Pro: $421.20/year ($35.10/month equivalent). Team: $1,609.20/year ($134.10/month equivalent). Starter has no annual discount.
Hosted plans do not automatically apply or merge repository changes. Separately configured checks may apply a candidate in an agreed workspace. Human review and the recorded execution boundaries remain explicit.
The monthly allowance counts admitted runs, not status or artifact reads. It is used at admission rather than at SUCCEEDED. Internal attempts remain in that run; a separately admitted rerun counts again. Provider billing is independent.
Repository command checks need a separately configured execution environment. A Pro or Team upgrade does not turn hosted command verification on; setup and execution-environment costs are agreed separately.
Economics · ESTIMATE ONLY. Compare a monthly hosted subscription with self-hosting under your own labor and cost assumptions. No savings have been measured.
Loading current monthly plan prices…
Plan prices are unavailable. No estimate can be calculated; check the current catalog below.
Choose a plan and complete all valid cost assumptions. Enter 0 explicitly for a cost that does not apply.
Estimate updated from your assumptions. This is not measured savings.
max(0, subscription + extra_provider - self_host_infra) /
                    hourly * 60
subscription, extra_provider and self_host_infra are monthly USD amounts; hourly is your labor value in USD per hour. The result is minutes per month, floored at zero.
This is the labor-time reduction required each month to break even on these inputs, NOT measured saved time or full TCO. We do not recommend plans from hours or PR counts.
Uses current monthly USD prices, not annual promotions. Taxes and model costs shared by both workflows are excluded. Setup and ongoing maintenance are not fully included; actual total cost may differ.
A review record helps you ask the next question: was the scope right, did the check run, did a test change, or did the execution environment fail?
Read the available failure evidence. Ambiguous failures remain review items, not proof that a patch is safe.
See the execution trail →A recorded pass covers the recorded checks only, not merge readiness. Human review is still required.
Repository checks require a separately configured execution environment. Hosted text review runs no repository commands. PASS covers recorded checks only; an unrun check remains unrun.
Open run history to review status, model attribution and available artifacts. Repository checks require a separate configured execution path.
A repository check depends on the selected environment and commands. Agree file access, network permissions and isolation before execution. Compare recorded results with CI; a pass in one environment is not a guarantee in another.
Temporary workspaces and retained reports are different data. Cleanup follows the runner configuration; execution records, logs and artifacts follow the documented retention policy.
Read the execution and evidence boundaries →Use the available execution evidence to decide what needs another look. These are review questions, not claims that every run detects every problem.
A before/after reproduction makes a fix easier to evaluate. If it is missing, name the other evidence and the behavior that still needs checking.
Compare recorded files and changes with the declared task scope. A configured validation path can make unrelated edits visible.
A removed or weakened test can change what a passing result means. Review test changes alongside the command outcome.
Review setup, network and test outcomes separately. Missing commands and timeouts can be classified, while ambiguous failures still need diagnosis.
These results concern their stated experiments. Read positive results, misses and methodological limits together; they are not a promise about customer repositories.
The AdaptOrch research paper studies task-adaptive multi-agent orchestration. The hosted product and the CEK repository-validation workflow have their own execution limits; paper results do not establish customer code correctness or hosted performance.
Read the AdaptOrch paper on arXiv →
AdaptOrch: Task-Adaptive Multi-Agent Orchestration in the Era of LLM Performance Convergence · Geunbin Yu · submitted 2026-02-18
Improvement and regression counts are available in the evidence JSON.
Every square is one recorded synthetic task. Green marks a passed check; a red outline marks an outcome that regressed from A to C.
Synthetic ledger, 30 tasks: paper baseline A versus robust + verifier C. Eight outcomes improved and one regressed. Both synthesis and verification differ; this is not a verifier-only comparison.
Local execution is measured. Human time savings are not. Keep those findings separate from an assumption-based cost estimate.
This experiment times CommandVerifier construction, execution and classification using trusted local controls, with no model API calls. It does not verify actual AI-generated patches.
Loading local measurement data…
Local data loaded. All outcomes, including mismatches, are shown below.
Measurement data could not be loaded. No results are shown; inspect the downloadable JSON instead.
Five fixed synthetic controls, repeated locally. Repetitions are not independent developers or tasks. Matches are counts of expected classifications, NOT bug-detection accuracy. Scroll the table horizontally if needed; keyboard users can focus it and use arrow keys.
| Control | Expected class | Observed classes (counts) | Median (milliseconds) | p95 (milliseconds) | Matches / attempts (counts) |
|---|---|---|---|---|---|
| Passing assertionClassification mismatch | — | — | — | — | — |
| Failing assertionClassification mismatch | — | — | — | — | — |
| Missing executableClassification mismatch | — | — | — | — | — |
| Deliberate timeoutClassification mismatch | — | — | — | — | — |
| Missing Python dependencyClassification mismatch | — | — | — | — | — |
Classification mismatch: the missing-dependency control expected ENV_ERROR but was observed as FAIL. Mismatched attempts remain in every timing summary and in the downloadable data.
Known limitation: the missing Python dependency was misclassified as an ordinary test failure. The classifier does not distinguish all environment failures from candidate failures.
These are not hosted round-trip latency measurements, a security-isolation test, or actual AI patch verification. Shared hosted command verification is disabled by default. The command component neither copies projects nor applies patches.
Protocol fixed before execution: 20 repeats per control, shuffled with seed 20260905; a fresh verifier per attempt, no cache, one command, and a 0.35-second timeout.
The five fixed controls are passing and failing Python assertions about 2 + 2, an absent executable, a 2-second sleep cut off at 0.35 seconds, and an absent Python import. These trivial fixtures are not AI-generated patches or real project test suites; their millisecond timings are not real project-test latency.
Trusted fixtures use a temporary working directory, default resource limits and no inherited environment. A temporary directory is not a clean project copy or a security boundary.
Monotonic wall-clock time covers verifier construction, command execution and classification. Measurement-program startup, report serialization and network latency are excluded.
All attempts are retained, including slow and error attempts. Median and nearest-rank p95 are descriptive statistics only: no significance test, generalized accuracy estimate or causal savings claim.
The JSON records revision, dirty-tree state, source hashes and environment metadata. This is an internal pre-execution protocol, not external preregistration or release approval.
No human study or customer savings data exist here. Local command timings cannot tell us how much review time a developer saves.
Before claiming savings, measure paired active review time on the same tasks with manual and assisted workflows, wait time separately, independent correctness, and actual subscription, provider, infrastructure, setup and maintenance costs. Include independent developers and repositories, randomize workflow order, and retain unsuccessful or slower runs.
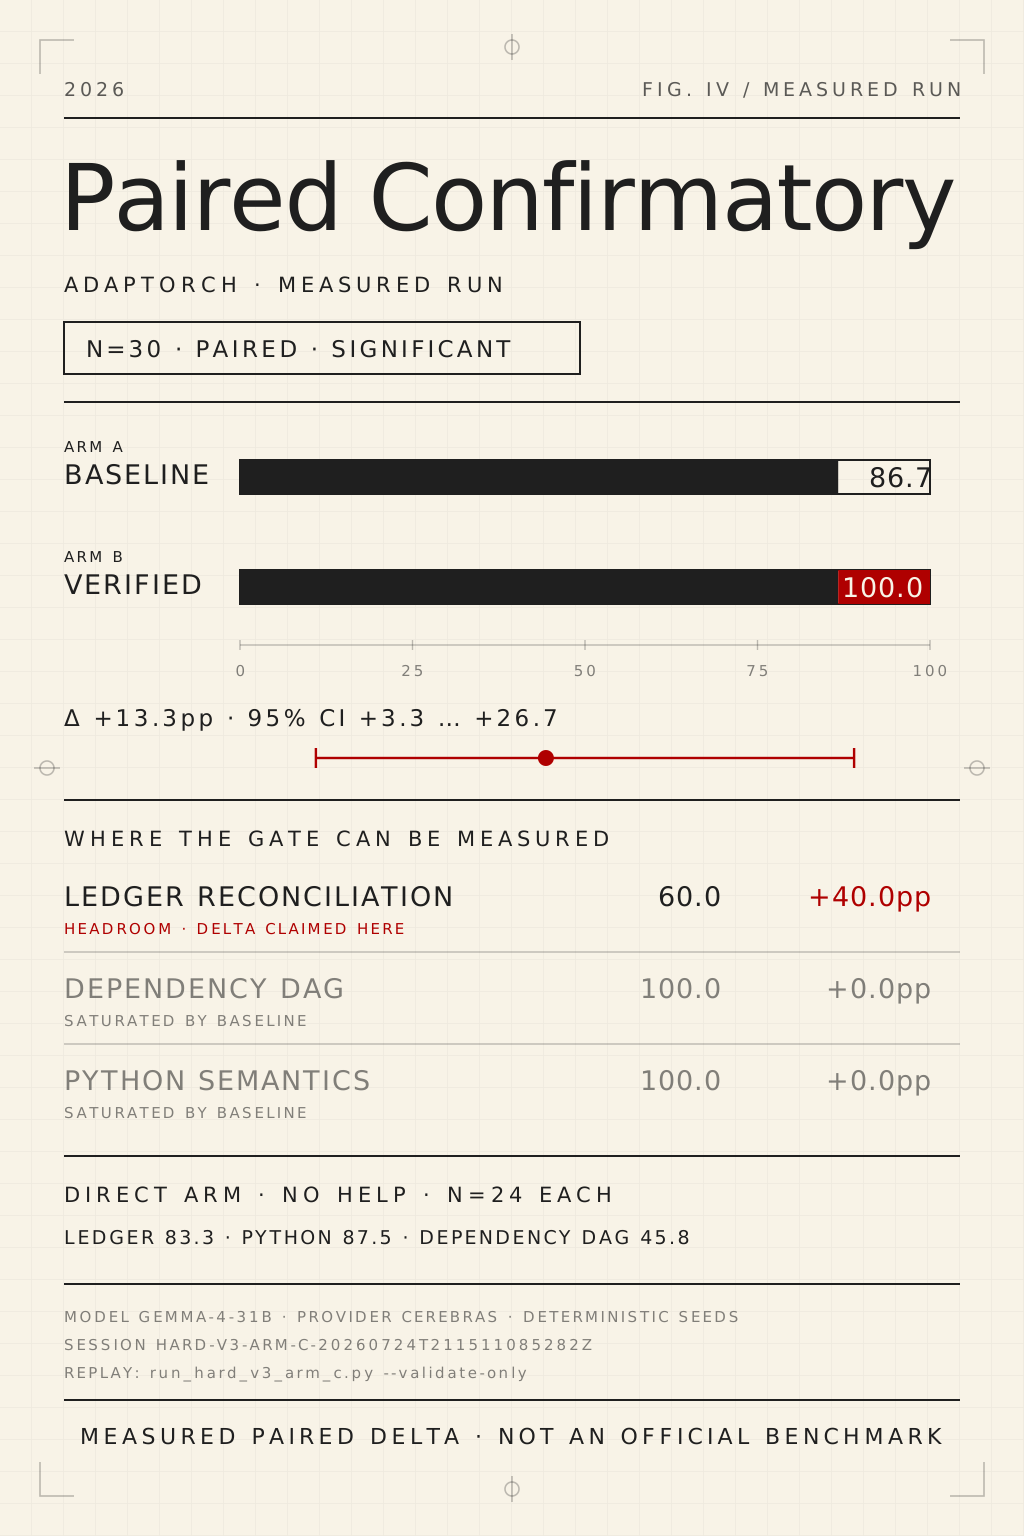
paired_confirmatory_ledger: 30 synthetic ledger tasks, one paired session. Baseline 86.7%, verified 100.0%, difference +13.3pp (95% CI +3.3 to +26.7). The aggregate paired verdict did not reach significance and the family gate did not pass: directional, not proven. This is separate from the A/C ledger comparison.
In this 20-puzzle ARC-AGI-2 run, the best single model scored 14/20 and the exact-answer vote scored 10/20. The vote cost more. This is one internal experiment, not a universal result.
The published aggregates include errors and truncation counts. GPT scored 16 tasks with 4 errors; Qwen scored 19 with 1 truncation. Those denominators differ from the best-model and vote arms.
Recorded model-call cost in USD, summed across the three member arms. Not a customer invoice or full TCO; additional charges are not established by this record.
three-way-20260826T142538Z
Public data contain aggregates, not per-task paired outcomes. They cannot independently establish how many answers were improved or regressed.
n = 20 · descriptive aggregate comparison, not a general performance claim.
A passing check covers only the conditions it executed. It does not establish overall correctness, safety, or behavior under untested conditions.
A run receipt reports the evidence that was recorded. A run without executed verification is not a test pass. The local experiment above measures command checks; it does not establish hosted patch execution or developer time savings.
We publish the negative outcomes too. In the synthetic ledger A/C comparison, eight task outcomes improved and one regressed. This compares both synthesis and verification settings, not the verifier alone.
If anything on this page promises more than we can show you, tell us. We will fix the page.
Submit model-backed runs through MCP or the API and inspect their records, outputs and available artifacts. Shared hosted command verification is disabled by default; repository checks need a separate execution environment.
No general correctness proof is provided. Check which verification actually ran and what evidence was recorded. A successful model run without executed tests is not a test pass.
The hosted workflow does not automatically apply or merge changes into your repository. A separately configured validation environment may apply a candidate in its agreed workspace for checking. You retain the review decision.
The current table reports local command-check timings on five fixed controls. Historical ledger timings measure a different operation. Neither establishes latency on your repository, hosted end-to-end latency, or saved developer time.
Missing executables and timeouts were distinguished in the local controls. A missing Python dependency was classified as an ordinary test failure. Failure labels need context; they are not a guarantee that every environment problem is diagnosed.
One admitted run uses one allowance unit. Status, usage and artifact reads do not create a new run. Completion is not the counting trigger, and a separately admitted rerun counts again. Hosted model usage is included; optional BYOK token charges are billed by your provider.
No. A model can finish without running a code check. Inspect the recorded commands, outcomes and skipped or untested areas. An AI-written explanation does not replace those records.
Use the documented MCP or HTTP connection path for your client. Authentication, a model run, and a repository check are separate steps; each needs its own confirmation.
A report presents the execution record and whatever verification evidence is available. Changed files, before/after tests and rerun details depend on the configured path; missing checks must stay explicit.
The public Starter connects to hosted AdaptOrch. Running a client locally does not make the service self-hosted. Contact us about a separate private-runner deployment for your network.
Hosted requests pass through AdaptOrch and the AI provider you configure. Review the data-transfer and retention policies before submitting private code. A private runner is a separate deployment, not a Starter default.
Automatic merging is not part of the default hosted offer. Any active gating must be separately configured and evaluated against the customer's own environment and review policy.
AdaptOrch is a hosted service for reviewing AI agent run records, model outputs and available verification evidence. Connect your coding tools through MCP or the API. Repository checks require a separately configured execution environment.
The paper is “AdaptOrch: Task-Adaptive Multi-Agent Orchestration in the Era of LLM Performance Convergence” by Geunbin Yu, submitted to arXiv on 18 February 2026 as 2602.16873. Its research results are separate from the hosted product and the CEK repository-validation workflow.
Read the AdaptOrch paper on arXiv →Inspect the run record, not only the final answer. Check what actually ran, which commands or tests were recorded, whether a reproduction failed before and passed after, whether unrelated files changed, and whether the test itself changed. A passing check covers only what it executed; it is not a correctness guarantee.
An agent run record is the stored history of one execution: the inputs, selected model, tool or command steps, outputs, status and available artifacts. AdaptOrch keeps hosted run records so a reviewer can inspect them later instead of relying on a chat transcript.
AdaptOrch is a review layer for AI coding agents, not another agent that writes code. It records execution evidence and available checks so a human can review the change. It complements code review and CI; it does not replace them or prove correctness.
Not a direct one. CodeRabbit and Copilot code review comment on a pull request. AdaptOrch is a review layer for AI coding agents: it records what the agent ran and which checks were available, so a person can review the change. It complements code review and CI, and you can use it alongside either tool.
See how AdaptOrch compares with other AI PR review tools →Not by default. The hosted text template reads the text you supply, such as the change explanation, your goal and existing checks, and returns a summary, missing information and review questions. It does not inspect code. Repository checks need a separately configured execution environment, offered as a PoC. Shared hosted command verification is disabled by default.
Starter is free with 50 admitted runs a month. Pro is $39 a month with 500 runs and 5 workspace users. Team is $149 a month with 2,500 runs and 15 workspace users. Hosted model usage is included in these plans. Optional BYOK usage is billed separately by your provider.
Start free. Keep your tools. Make your own call.
Start freeContact usTell us what is hard to verify. We will first check the execution constraints, then agree scope, deliverables and price before any repository work.